Bonolo Mnyameni · data scientist · Warsaw

I make data make sense.

B.Sc in Mathematics, then more than four years building clinical data and AI at AstraZeneca, in regulated pharma where a wrong number is not an option and every result has to survive an audit. Now Zastron Labs, one person, in Warsaw.

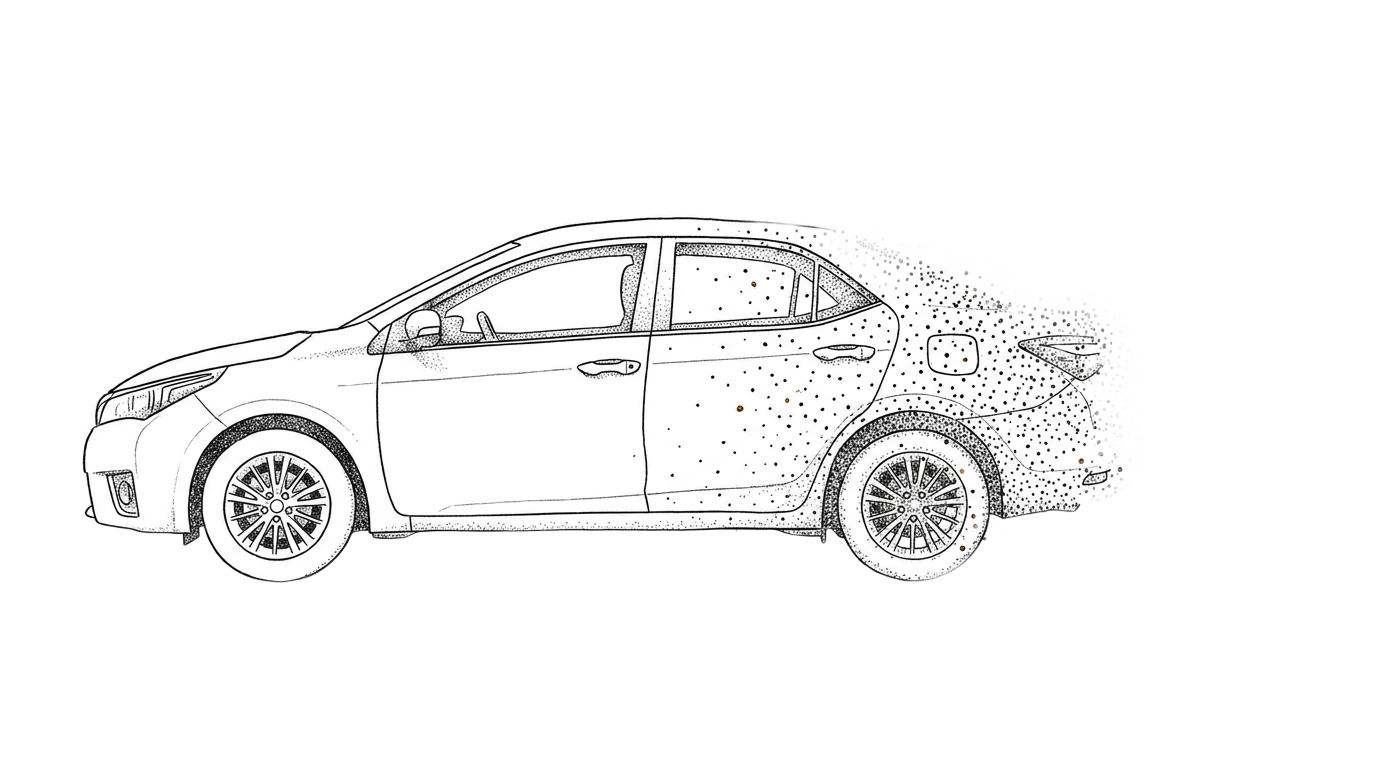
That is 24 992 dots, one for every Toyota Corolla E170 registered in Poland, by build year. Source: CEPiK

Data engineering and analysis

four projects

01
  • Python
  • REST API (CEPiK)
  • PostgreSQL
  • resumable ETL

Counting every Corolla in Poland

Poland's national vehicle registry will tell you, exactly, that 89 450 cars of one platform are on the road: 24 992 Corollas and 64 458 of its twin, the Auris.

Poland publishes its vehicle registry as open data, around 18 million vehicles. I needed one model family out of it. Scanning everything would have taken most of a day, so I wrote a probe script first and proved the API supports a server side make filter. That cut the national census to about half an hour and, more importantly, made the count exact rather than sampled.

The collector is resumable, with a checkpoint per window, and a window only commits once it has been fully paged. Government APIs drop connections, and a census that cannot be resumed is a census you will never finish. Aggregates only: the raw rows never leave the machine, there is no personal data, and every surface that shows a number credits the source.

backend/data/collect_cepik.py
KEY SPEEDUP: CEPiK /pojazdy supports a SERVER-SIDE make filter `filter[marka]=TOYOTA`
(proven by probe_cepik_filter.py). So instead of scanning all ~18M vehicles to find
Toyotas, we pull ONLY Toyotas (~7-13% of the fleet) -> the full national census runs
in ~20-30 min instead of ~6-10 h, and the count is EXACT (not sampled).

CTX = ssl.create_default_context(); CTX.set_ciphers("DEFAULT@SECLEVEL=1")  # CEPiK weak DH key

PROD_YEARS = {str(y) for y in range(2013, 2020)}     # E170 generation 2013-2019
LIMIT = 500
SLEEP = 0.7                                  # < 100 req/min, < 20 req/s
1 070 191Toyota records scanned
89 450cars on the E170 platform
16regions covered
0raw rows leaving the machine

See it on the live dashboard Read the full method

What the census actually found

Every Toyota on Polish roads, by model, all generations. The two highlighted bars are where the platform I wanted was hiding.

Yaris Corolla RAV4 Auris C-HR Avensis 260 037 225 468 111 403 89 558 87 041 70 051

Source: CEPiK national census, full pass, 1 070 191 Toyota records. Bars are all generations; the E170 platform slice inside them is 24 992 Corolla plus 64 458 Auris.
02
  • Python
  • stream processing
  • 5 GB of zips
  • PostgreSQL

When do cars actually start failing?

221 847 real inspection results show exactly where the failure curve bends as mileage climbs. It is not a straight line, and it does not bend where people assume.

The UK publishes the result of every MOT inspection it carries out. The catch is that the car I care about, the Corolla E170, was sold in Britain as the Auris, and a UK "Corolla" from 2019 onwards is the next generation entirely. Include it and the sample is quietly poisoned. So the dataset is the platform twin, and it is labelled as a proxy on every single surface that shows it, because a number you have to explain is better than a number that is wrong.

The zips are too large to extract comfortably, and the 2023 archive uses a compression format the Python standard library cannot read at all, so the pipeline streams the CSVs straight out of them. Miles convert to kilometres. Only initial tests count, never retests, because retests would flatter every figure on the page.

backend/data/process_mot.py
- Pipe-delimited ('|'). UK odometer is MILES -> converted to km (x1.60934).
- Fail rate uses INITIAL tests only (test_type 'NT'), not retests ('RT'),
  the standard MOT methodology. Pass = P/PRS, Fail = F, abandoned excluded.
- Failure reasons = test_item rows with rfr_type_code 'F' (major/fail; 'M'
  minor + 'A' advisory don't fail) on those E170-platform NT tests.

def is_e170_platform(make: str, model: str, year: int | None) -> str | None:
    """Return 'auris' / 'corolla' if this row is the E170 platform family, else None."""
    if make != "TOYOTA" or year is None:
        return None
    if "AURIS" in model and 2013 <= year <= 2019:
        return "auris"
    if "COROLLA" in model and 2013 <= year <= 2018:   # 2019+ Corolla = E210, exclude
        return "corolla"
    return None
221 847initial tests analysed
28 892of them failed
13.02%overall failure rate
2.3xrisk from lowest to highest band

See the risk readout Read the full method

Failure rate by mileage

The honest detail most charts would smooth away: the 200 000 to 260 000 band comes in fractionally below the one before it. Real data is lumpy, so the line is drawn as measured.

5% 10% 15% 20% 8.12% 14.03% 16.42% 16.28% 18.33% under 80k 80k to 140k 140k to 200k 200k to 260k over 260k 74 061 tests 75 846 32 461 16 447 22 976

Source: UK DVSA MOT anonymised bulk, 2023 and 2024. Auris E180 platform twin used as a proxy for the Polish Corolla E170: mechanical failures transfer, body specific findings differ.

03
  • Python
  • SQL
  • idempotent seeds
  • adversarial review

What is a used car actually worth?

Every one of the 119 value deductions in the model survived an independent attempt to refute it before it was allowed in.

The valuation grid is 84 baseline cells, one per year, engine and mileage band, plus 119 researched deductions in zloty, one for every inspection finding at every severity. The research ran as a governed fleet: finders proposed numbers, a matching set of verifiers were told to break those numbers, and a plausibility auditor held back anything that could not be defended.

The part I am most pleased with is not the model, it is the loader. It refuses to half load. Row count, currency, price sanity and severity ordering are all checked inside the transaction, and any violation rolls the whole thing back. A worse fault priced above a milder one is not a rounding error, it is a broken model, and the database will not accept it.

backend/supabase/seed/013_fmv_deductions.sql
-- Self-checks: abort on a dropped slug, a banned dash, a bad band, or broken
-- severity ordering within an item.
DO $$
DECLARE bad integer; cnt integer;
BEGIN
  SELECT count(*) INTO cnt FROM fmv_deductions WHERE source = 'fleet_curated_2026_06';
  IF cnt <> 119 THEN
    RAISE EXCEPTION 'expected 119 fmv_deduction rows, found %', cnt;
  END IF;

  SELECT count(*) INTO bad
    FROM fmv_deductions a
    JOIN fmv_deductions b
      ON a.inspection_item_id = b.inspection_item_id AND a.severity < b.severity
   WHERE a.pln_low > b.pln_low OR a.pln_high > b.pln_high;
  IF bad > 0 THEN
    RAISE EXCEPTION '% severity-monotonicity violations (a milder grade priced above a worse one)', bad;
  END IF;
END $$;
84baseline valuation cells
119verified deductions
18research agents, half of them hostile
0entries shipped unverified

Move the mileage slider Read the full method

What the market pays, by build year

The band is the honest part. There is no single price for a used car, so the model carries a range and shows it, rather than inventing a confident number.

20k 40k 60k 80k 2013 2014 2015 2016 2017 2018 2019 32 000 to 41 700 zl 59 600 to 77 400 zl

Source: fmv_baselines, 84 rows, 1.6 Valvematic between 80 000 and 130 000 km. Manual market curation, sample sizes 8 to 18 per cell. PLN.

04
  • Python
  • public price research
  • adversarial re-check
  • PostgreSQL

A fair price for a car part

Two of the 32 researched parts never shipped, because the audit could not make their price bands defensible. The gaps are the proof that the rest is real.

Thirty price bands for common parts, in zloty, quality aftermarket rather than the cheapest thing on the shelf, each one independently re-verified against public Polish retailers before it was allowed to load. Where a genuine Toyota part has a published price, the row carries that too, so an owner can see the actual gap rather than being told which to buy.

The two that did not make it are the interesting ones. One sensor had a band that would have quietly priced the wrong variant of the part, and one exhaust component simply does not exist as a specific aftermarket item for this body shape, so any band would have been a guess dressed as a fact. The decisions are written into the generator rather than applied by hand, which means a re-run reproduces the same result, refusals included.

backend/data/parts_prices_to_seed.py
The AUDIT RESOLUTIONS the auditor demanded are encoded here, not hand-applied,
so a re-run reproduces the exact same seed (D008 discipline):
  * DROP lambda_sensor      - its 130-400 band prices universal/post-cat sensors
    while the genuine UPSTREAM wideband sensor (the part an honest garage quote
    is usually for) costs 680-1450 zl; one row cannot carry both without
    misleading the owner. Confidence was 'low'. Held back, not shipped.
  * DROP exhaust_silencer   - no E170-SEDAN-specific aftermarket rear box exists
    at any major Polish retailer (finder AND verifier confirmed independently);
    the band was a platform-twin proxy. Confidence 'low'. Held back.
30price bands shipped
2held back by the audit
17research agents
100%re-verified before loading

See the parts readout Read the full method

Aftermarket band against the genuine part

Amber is the quality aftermarket range. The dark tick, where one exists, is the published genuine Toyota price for the same item.

Engine oil Oil filter Air filter Cabin filter Spark plugs Battery Front brake pads Front brake discs Rear brake pads Front struts Drive belt Coolant 0 200 zl 400 zl 600 zl

Source: 32 part curated research, 30 shipped. Part only, fitting not included. PLN.

Product

one project

05
  • Flutter / Dart
  • Supabase
  • PostgreSQL + RLS
  • 29 SQL migrations
  • 258 automated tests

Cario, shipping all of it as a product

The whole backend has no API server. Security is row level rules inside the database itself, and the app talks to Postgres directly.

Everything above exists because it ships inside something real. Cario is a maintenance, inspection and valuation companion for one car, deliberately vertical: one model, one country, measured properly before anything wider. Twenty eight screens, feature complete, camera scanning of the vehicle number with recognition running on the phone rather than a server, and data export and deletion built in from the start rather than bolted on.

Every schema change is a numbered migration, which means the database can be rebuilt from zero and arrive in exactly the state it is in now. That is the same discipline regulated pharma taught me: if you cannot reproduce it, you do not really have it.

28screens, feature complete
258automated tests, all passing
29numbered migrations
1car, done properly

Read the full story Or go straight to the live numbers

Cario, the maintenance and valuation app for the Toyota Corolla E170, rendered as a field of dissolving points
Cario. Not yet on the app stores; the numbers behind it are open on the live dashboard.

Research

one project

06
  • Python
  • pandas / numpy
  • pytest (86 tests)
  • 1 minute FX data
  • 4.45 GB, licensed
  • deflated Sharpe

The lab that said no, eight times

The closest hypothesis was genuinely profitable, plus 10 to plus 19 basis points per episode across 492 out of sample episodes, and the lab still killed it. Profit is not the same thing as proof.

I built a backtesting laboratory whose entire product is answers I can trust, then pointed it at eight of my own trading ideas across currencies, crypto, metals and equity indices. Every hypothesis was pre-registered before it touched data: a falsifiable claim, a statement of who is on the other side of the trade losing money, explicit kill criteria, and a fixed budget of attempts. Every run lands in an append only ledger, so the statistics stay honest about how many things were tried.

Two tripwires keep the instrument itself honest. A strategy with no edge must earn nothing, and a strategy that cheats by peeking one bar into the future must be caught loudly. I calibrated in both directions with planted synthetic edges: it never cried wolf across 140 checks, and it reliably finds a real edge once that edge is worth roughly twice what trading costs.

The verdict after eight hypotheses was eight kills, no false positives, and a written reason for every death. That is the skill I am actually selling: knowing when the answer is no, and being able to prove it.

edge-lab, operating rules
Gate A: a zero-edge coin on zero-drift bars must lose net almost exactly
        what it pays in costs, ~zero gross.
Gate B: a deliberate lookahead signal must produce an absurd Sharpe
        (leaks are VISIBLE), and shifting it +1 bar must destroy it.

Hard rule 1: never modify tests to make them pass.
Hard rule 5: the trial ledger is append-only. Every backtest counts
        against the deflated-Sharpe bar, forever.
8hypotheses tested
8killed, with reasons
0false positives in 140 checks
16.5years of 1 minute data

Read the code and the paper trail Read the full method

The kill board

Eight pre-registered ideas, eight verdicts. A lab that never kills anything is not a lab, it is a sales pitch.

H1no
H2no
H3no
H4no
H5no
H6no
H7no
H8no

H4 is the highlighted one, and the hardest to let go of. It was profitable, plus 10 to plus 19 basis points per episode over 492 out of sample episodes, and it still fell short of the bar once every earlier attempt was counted against it.

Statistics and charts are our own. The underlying 1 minute price data is a licensed purchase and is never redistributed here.

The person doing the work

one of me

Background and skills

Zastron Labs is one person, and every project above was built by him.

I am Bonolo Mnyameni. I work from Warsaw, in English and Polish, and the person you email is the person who does the work. There is no account manager and nobody to hand you off to.

  1. Zastron

    A small town in the Free State

    South Africa. Above it stands Aasvoëlberg, and high on that rock is a hole worn straight through solid stone by nothing but water and time. That is the eye in the logo, and it is the method.

  2. B.Sc

    Mathematics

    The reason I reach for a distribution before I reach for an opinion.

  3. 4 yrs +

    Clinical data and AI, AstraZeneca

    Regulated pharma, where a wrong number is not an option and every result has to survive an audit. That is where the habits on this page come from: numbered migrations, reproducible loads, and a written reason for every decision.

  4. 2026

    Founded Zastron Labs sp. z o.o., Warsaw

    A registered Polish company, one founder, no agency. Cario is its first product, and the six projects above are what the first year looks like.

What I actually work in

Each of these is claimed only because something on this page proves it.

Python
The registry collector, the inspection stream processor, every data generator, and the backtesting lab. Projects 01, 02, 03, 04 and 06.
SQL and PostgreSQL
A loader that asserts row counts, currency and severity ordering inside the transaction and refuses to half load, plus 29 numbered migrations behind Cario. Projects 03 and 05.
Data engineering
A resumable census over a national registry, and a pipeline that streams 5 GB of archives without extracting them. Projects 01 and 02.
Statistics and validation
Pre registration, an append only trial ledger, significance adjusted for how many things were tried, and calibration against planted synthetic edges. Project 06.
Data visualisation
Every chart on this page, drawn by hand from the source figures rather than pasted from a tool, including the 24 992 dots at the top.
Flutter and Dart
A feature complete mobile app: 28 screens, 258 passing tests, on device text recognition, and data export and deletion built in. Project 05.
How I work
Adversarial verification, reproducible loads, and limitations stated in public. Two of 32 researched parts were dropped for being indefensible, and eight of eight trading ideas were killed. The gaps are the proof.

The longer version LinkedIn

Tell me what is not adding up.

No pitch needed. Describe the problem in plain words and I will tell you honestly whether I can help, and whether it is even worth paying someone to.